
When a trace is scored
Scoring is queued the moment a trace’s root span lands. A trace is live while spans are still arriving or while it has no root span yet, completed once the root span has landed, and interrupted when no root arrives within the settle window (TRACE_SETTLE_SECONDS, default 600 s — a killed run never exports its root, because the root ends last). A sweep every 120 s re-checks the last two hours, 200 traces at a time, for traces the immediate pass missed, including interrupted ones; a finished pass is recorded per trace with its verdict counts and cost, and a pass that left verdicts deferred or errored is retried. The trace list and the trace header show the status.
A trace is skipped as a whole, never errored, when it has no spans, when it is an orphan fragment, when no span resolves a capability, when its root span carries an error status and it carved a single unit, or when the capability has no active eval set or the set has no trace-scoring members.
Units
A unit is the slice of a trace that gets its own verdicts. The carve is a precedence lattice; the first tier that applies wins:
Tiers 1–3 exclude the root. In a multi-entry trace, interior turn units fold into the enclosing execution as step coverage rather than scoring twice; a run boundary that encloses turn slices is offered again as a run-grain surface and kept only when a run-grain behaviour binds it. A single
function span that starts its own trace outside any declared boundary is an orphan fragment and is skipped; a lone untyped span still scores.
The span carrying overmind.delivery = true — deliver() in the SDK — is the unit’s terminal deliverable; without it the platform picks the terminal span heuristically.
Behaviours and bindings
A behaviour is one contract a capability performs, minted byovermind sync from the trajectory map: an entry anchor, the ordered anchor segments that follow it, its tool set, and its terminal. Behaviours keep their identity across syncs through their key.
Each unit binds to one behaviour, recorded as a task execution with a binding_source:
declared— the span carriedovermind.behaviour.key(overmind.task("<key>")). A declared key whose grain disagrees with the unit — a turn’s key stamped on a whole run — is refused and falls through to the anchor join, with adeclared_grain_mismatchflag on the execution.anchor_join— the unit’scode.namespace/code.function.namestamps matched the behaviour’s anchors; the binder tolerates dotted-suffix differences and prefers the version analysed at the trace’svcs.ref.head.revision.unbound— nothing matched. The execution still materialises, and the unit still scores against the capability’s set; members bound to a behaviour are skipped on it.
Verdicts and the execution score
The eval set’strace_scoring members run per unit. Every evaluator carries a claim — a type and a grain — and the claim decides how its verdict composes:
- Safety claims cap the score: the composite never reads higher than the worst cap verdict, and the marker names
cap_evaluatorandfailure_mode_cap. - Conformance and verification claims flip their own verdict’s
passedwhen they fail; no member vetoes the rest. - Progress, quality, and grounding claims are scoring leaves.
- Every verdict feeds one of three phases by grain — steps (weight 0.25), trajectory (0.25), and output (0.50) — and an empty phase’s weight is redistributed proportionally to the others.
- Two output-phase verdicts more than 0.5 apart never average silently: the marker carries a
conflictwith the lane, the spread and both members’ values, and the Console shows it on the row.
Verdict row: evaluator, target span, typed outcome, score, passed, explanation, unmet clauses, scope, grain, gate, sub_scores, identifier, cost and latency. Verdict rows are the source of truth — every detail surface reads them over GET /api/verdicts/. The unit’s span keeps only the composed markers, written to feedback_score.trace_scoring as a derived cache the list views read:
_execution.score (0–1) is the composite the Console shows as the Score column. A trace with several entry-point invocations scores each unit onto its own span; the root span gets only an invocations summary entry ("2/2 invocations passed") and an _execution that averages the unit scores.
Verdict outcomes are scored, abstained, not_applicable, or error, and only scored verdicts feed the composite. A member whose evidence the trace cannot supply abstains rather than guessing; a member skipped for its grain, a behaviour filter, or an interrupted run persists a retryable not_applicable row whose unmet list carries skip:grain, skip:behaviour-filter, or skip:interrupted. A skip row never settles its series: it is overwritten when the member dispatches on that unit. An interrupted skip is the one case that overwrites a real verdict, since a delivery grade on a run that never delivered is stale by rule.
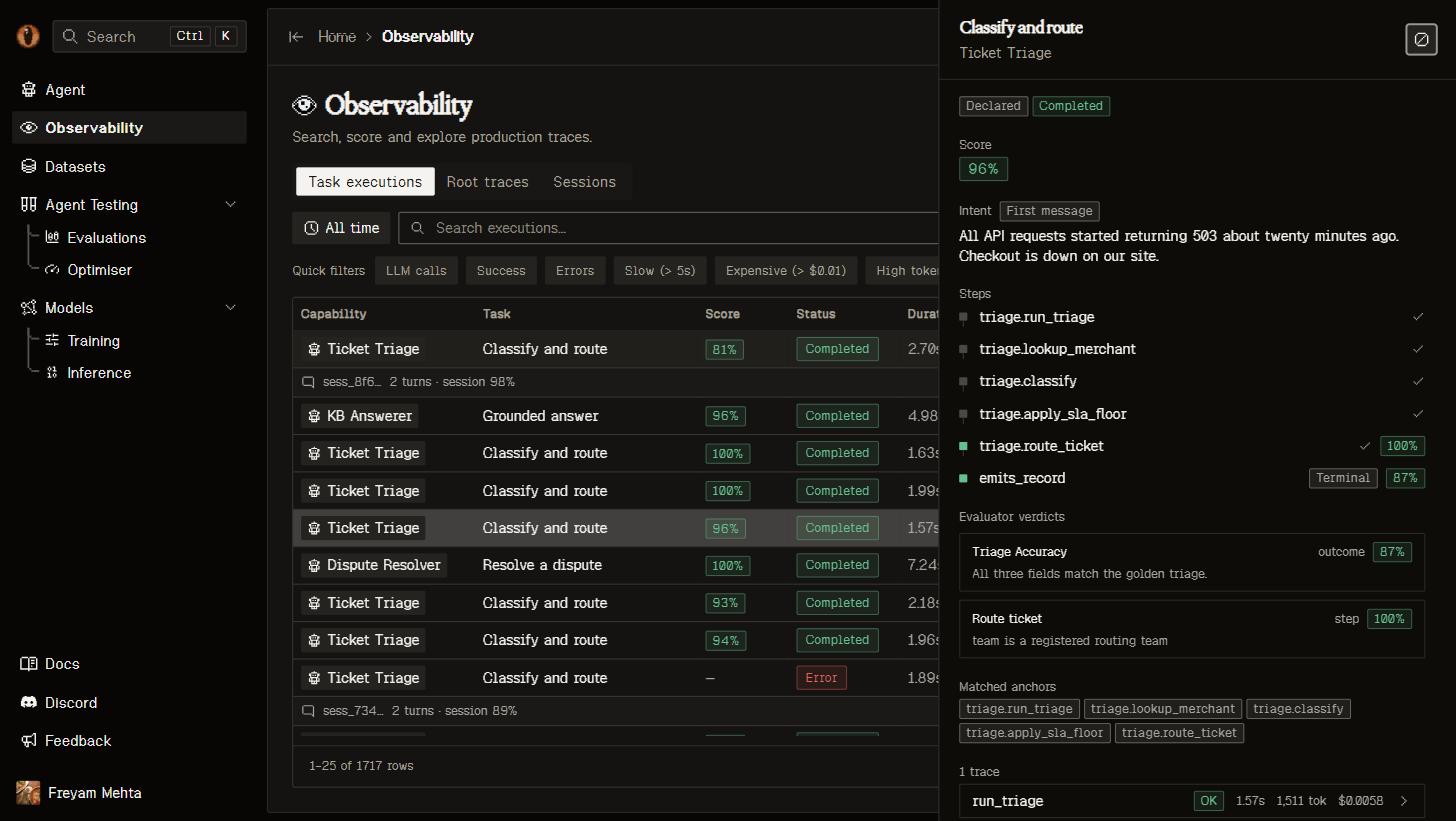
An execution in the Console: the intent, the route through the behaviour's anchors, and every verdict with its reasoning.
Session scores
Traces sharing aconversation.id form a session. Each scored turn appends conversation events to a ledger: ask_opened, ask_superseded, ask_reprompted, delivered, delivered_wrong, refused, and parked (a turn that stopped to confirm before a gated write). The session score is a fold over that ledger: an open produce ask, or a produce ask delivered wrong and never delivered afterwards, zeroes the session; a re-prompt reopens a refused or superseded ask. The execution carries session_score and session_rationale, and the Sessions view rolls them up.
Runtime expectations from the SDK
The SDK can declare evidence at run time; the platform reads it from span events and evaluates it server-side:
See the Python SDK for the calls.
Reading executions over the API
/api/task-executions/: project, capability, behaviour, binding_source, trace_id, status, started_at__gte/lte, received_at__gte/lte, min_duration_ms, max_duration_ms, has_error, service_name, operation, span_type, status_code, model, has_model, total_tokens__gte/lte, total_cost__gte/lte. The list row carries behaviour_key, success_score, session_score, session_rationale, route_flags, terminal_kind and scoring_pending. The detail adds observed_route (the anchors the unit hit), step_results (per-step verdicts), user_intent, and the unit’s composed markers: execution_score, conflict, skipped_members, and the flow (each contract anchor with its match and verdict). Over MCP the same reads are query_task_executions and query_failures.
GET /api/verdicts/ lists Verdict rows newest-first. Filters: target_id, target_id__in, target_kind, evaluator_name, outcome, and trace_id — every span-target verdict of one trace in a single call.
GET /api/task-executions/conversation-turns/?conversation_id={id} returns one row per turn of a conversation, assembled server-side from the executions and their traces’ spans: the turn’s intent, input and output text, execution and session scores with the session rationale, the task state (outstanding asks, delivered-wrong flag), per-step results, and the tool calls with their inputs and outputs.
GET /api/behaviours/coverage/?capability={id} returns, per behaviour, the outcome evaluators and whether the outcome is covered, plus each anchor segment with the step evaluators bound to it.